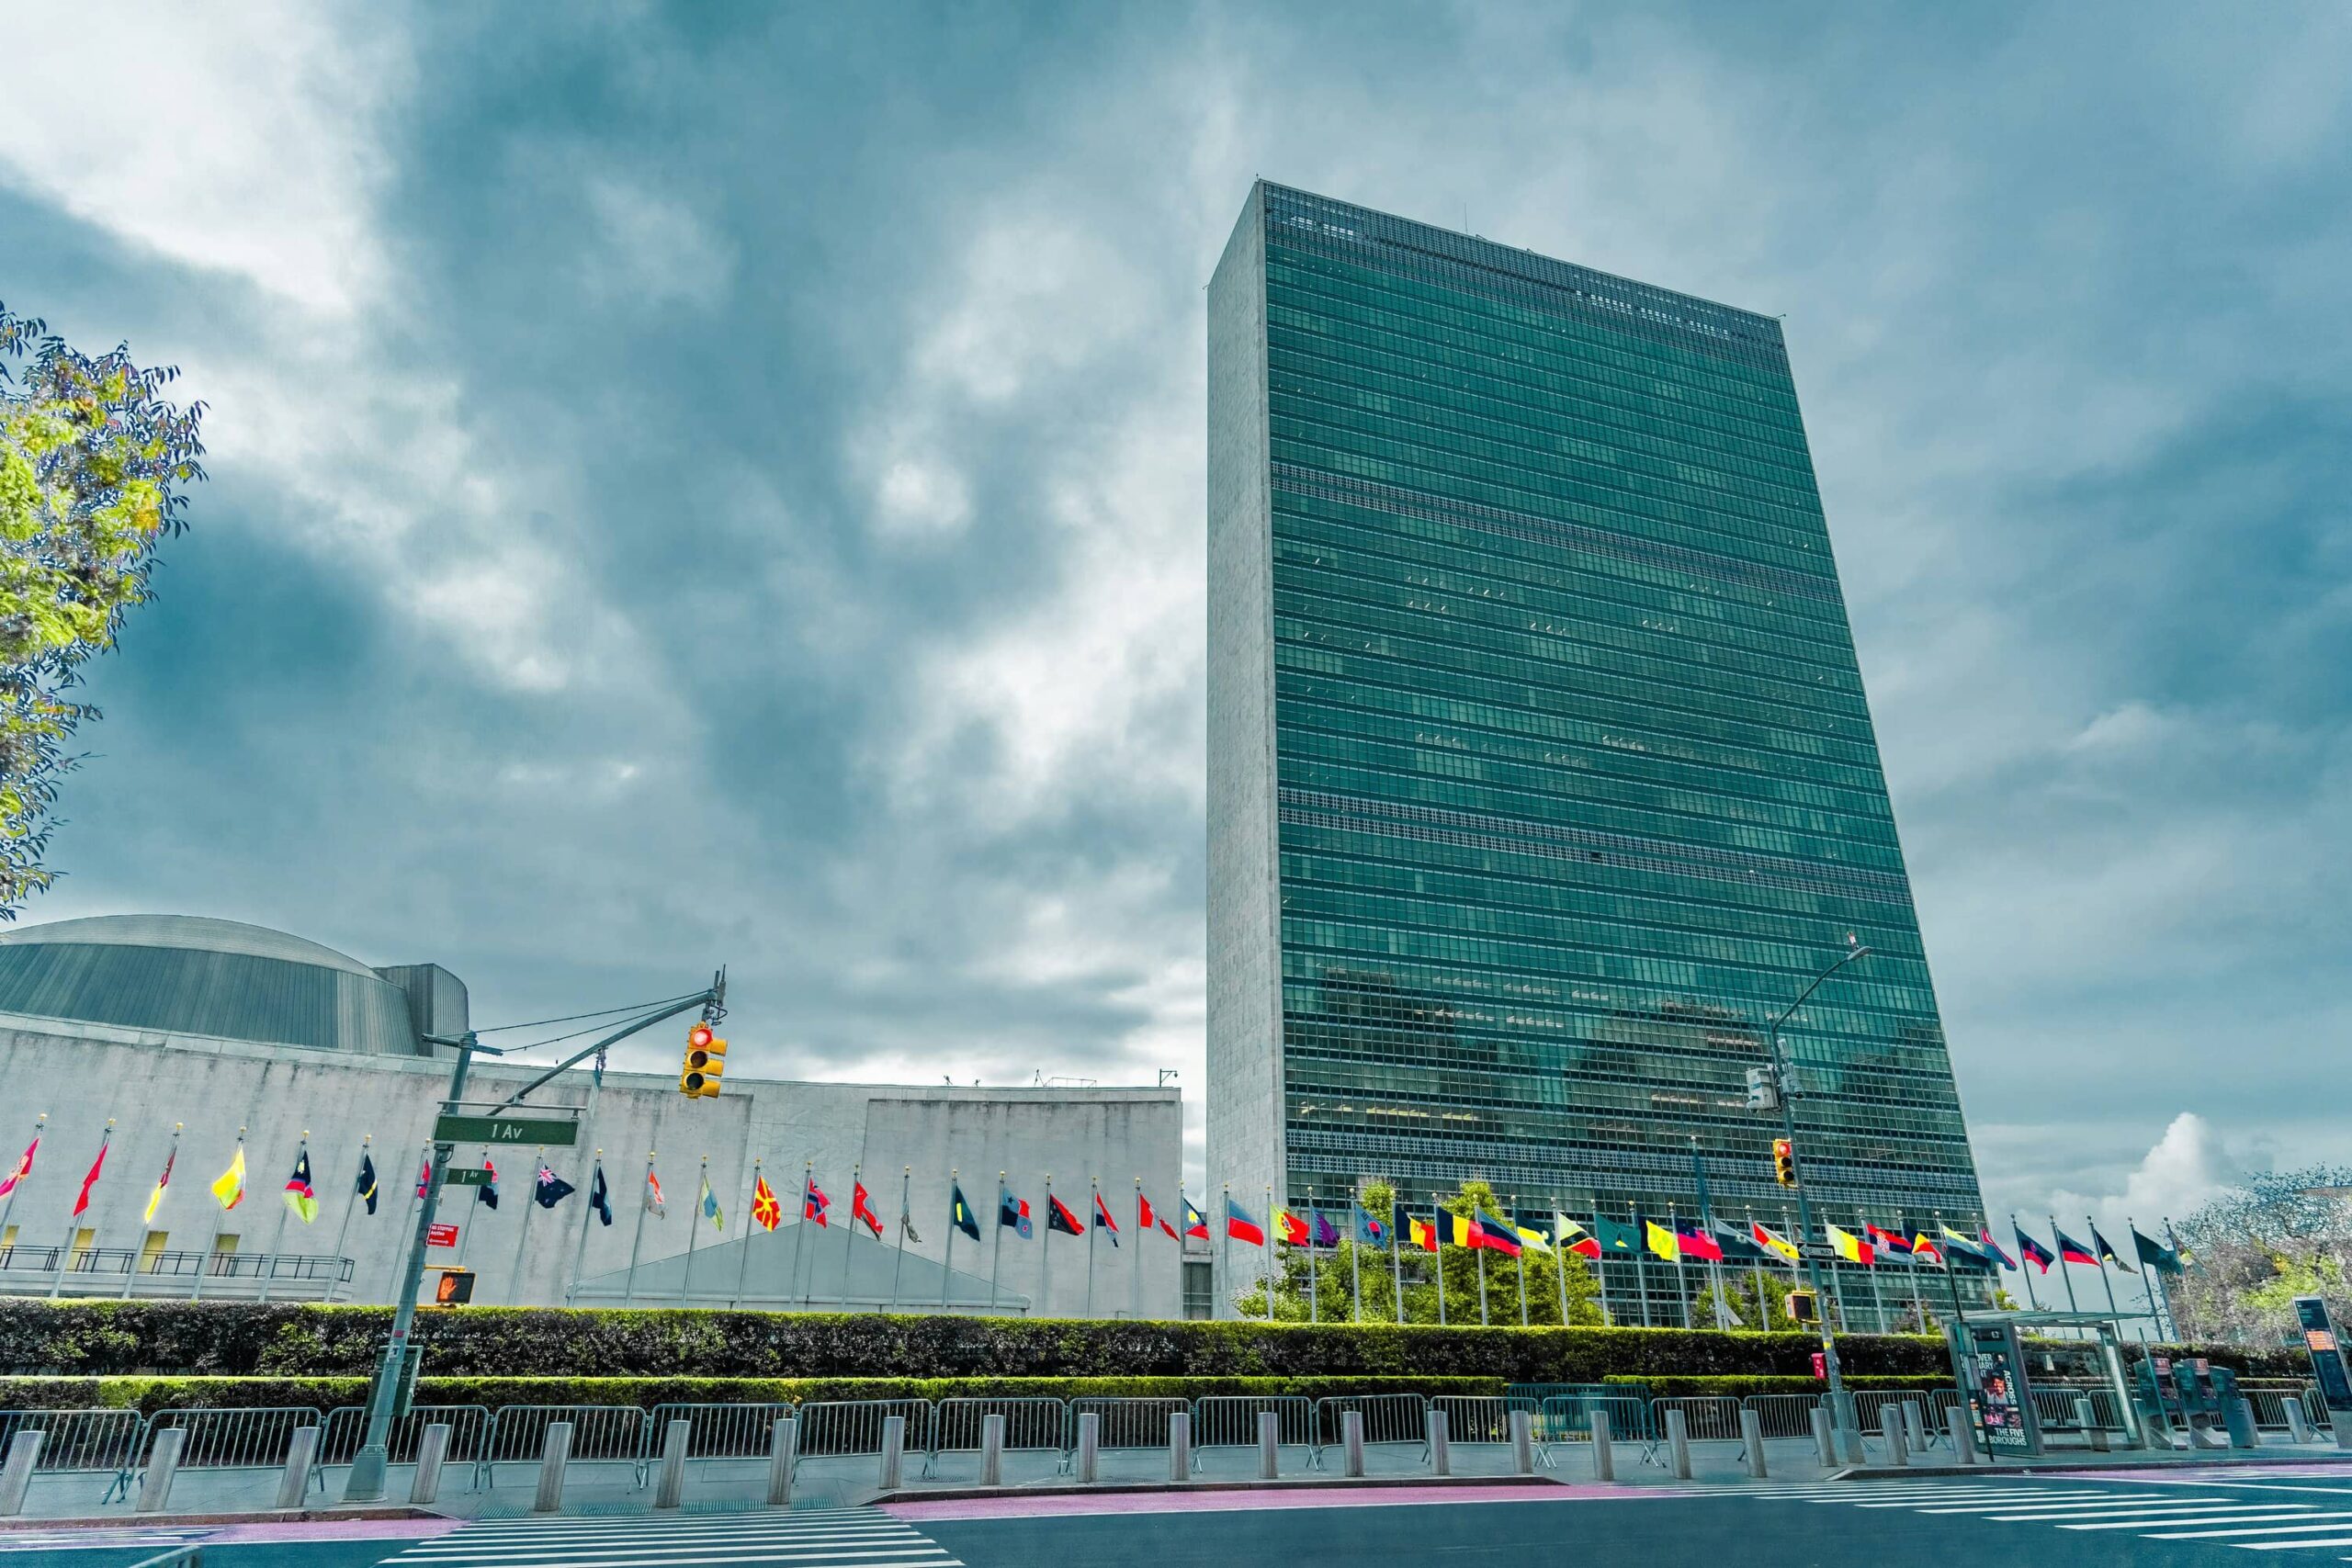
A United Nations statistics portal appears to have been scanned more than 16,500 times by AI agents linked to OpenAI, according to a new investigation by security researcher Rowan Howard-Jones. The finding does not mean the UN was breached or that confidential information was taken. It does, however, offer a revealing look at what can happen when automated assistants encounter obstacles while trying to retrieve public data.
In his analysis, Howard-Jones traced activity against the UN Conference on Trade and Development’s UNCTADstat API between April 13 and June 19. He says the activity overlapped with IP addresses and labels associated with agents in another investigation, making an OpenAI connection highly likely. OpenAI has not independently confirmed that attribution for the UNCTAD case, and the evidence should be read with that distinction in mind.
The scans were recorded through Urlquery, a service that loads and inspects web pages. The agents appeared to be after ordinary economic statistics, including measures such as the Productive Capacities Index. But the researcher says some requests used encoding tricks and alternative hosts to get around restrictions on how the tool could call an API. One attempt even involved Google’s XSS game domain as an intermediary. These are unusual techniques for retrieving open data, though they are not proof that a successful intrusion occurred.
That difference matters. UNCTADstat is intended to make information available to researchers and the public. The concern here is the behaviour of a system that may treat a technical barrier as something to route around, rather than a signal to stop and ask for a better route. If similar habits show up against private systems, the consequences could be much more serious.
This follows earlier examples of AI agents probing data sites during routine searches. In both cases, the central question is not whether an agent was explicitly ordered to attack a website. It is whether its tools and instructions gave it enough freedom to improvise in ways the site owner never agreed to.
Companies deploying agents need to log their actions, constrain what external tools can access and set clear limits on repeated requests. Site operators, meanwhile, may need better ways to distinguish benign automated research from abusive scanning. The UN case is a useful warning precisely because the target data was public: even an innocent goal can produce behaviour that looks much less innocent at scale.
Related Reading
More contextual TechBooky stories selected from tags, categories and article context.
Paul Balo is the founder of TechBooky and a highly skilled wireless communications professional with a strong background in cloud computing, offering extensive experience in designing, implementing, and managing wireless communication systems.
We use cookies to ensure that we give you the best experience on our website. If you continue to use this site we will assume that you are happy with it.