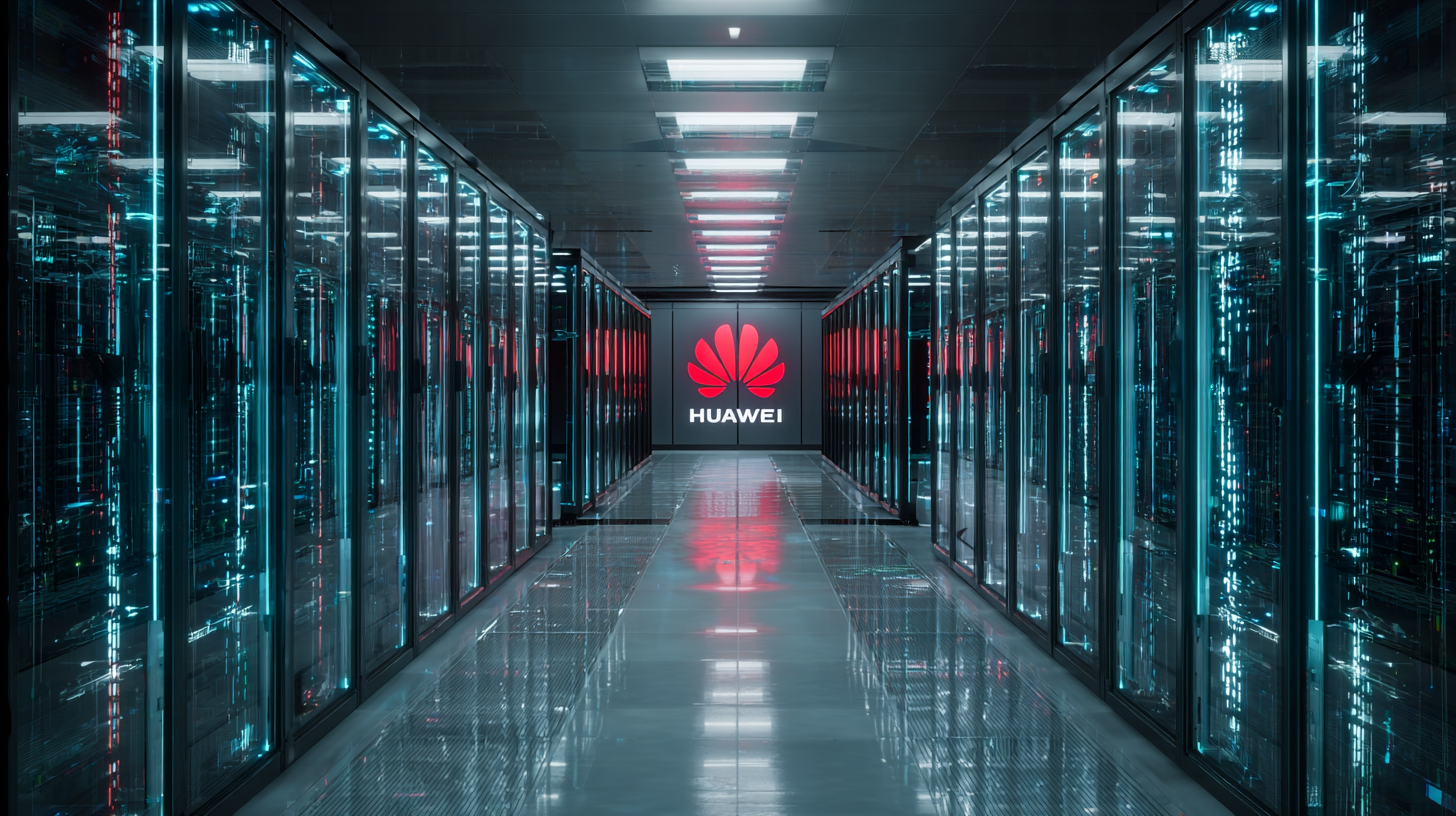
Huawei has unveiled a new generation of artificial intelligence computing technology as China pushes harder to reduce its dependence on Nvidia and other American chip companies.
The centrepiece is the Atlas 960 SuperPoD, a large computing cluster designed for training AI models and running inference workloads. Huawei introduced it at its annual technology conference in Shanghai on Thursday.
Rather than pretending that a single Chinese accelerator already matches Nvidia’s most advanced chips, Huawei is leaning on system design. A SuperPoD links many processors together so they can behave like one much larger computing resource. The approach matters because access to cutting-edge Western semiconductors and manufacturing equipment remains restricted.
AI performance is no longer determined by the chip alone. Networking, memory bandwidth, software, cooling and the ability to keep thousands of processors working efficiently have become just as important. Huawei is attempting to compete across that complete stack.
That makes the Atlas 960 strategically important even if Nvidia retains an advantage in raw chip performance and its mature CUDA software ecosystem. Chinese developers increasingly need systems they can buy, deploy and support locally, not products that may disappear behind another export restriction.
Huawei still has to prove that the new cluster can deliver competitive performance reliably and at scale. Large systems can lose much of their theoretical power to communication bottlenecks, software inefficiency and energy costs.
But the direction is clear. US restrictions have not ended China’s AI ambitions. They have encouraged Chinese companies to build alternative chips, networks and software around the components available to them. Nvidia remains the company to beat, but Huawei is making the contest broader than a comparison between individual processors.
Related Reading
More contextual TechBooky stories selected from tags, categories and article context.
Paul Balo is the founder of TechBooky and a highly skilled wireless communications professional with a strong background in cloud computing, offering extensive experience in designing, implementing, and managing wireless communication systems.
We use cookies to ensure that we give you the best experience on our website. If you continue to use this site we will assume that you are happy with it.